The fundamental step to work on a Machine Learning project is to state well the problem you want to solve. Usually, the problem definition comes from a business or a domain like marketing, finance, medicine, engineering, and others. Thus, we must state the problem in terms of the business or the domain and then map it to a typical Machine Learning task.
(more…)Author: Rodolfo Mendes
-
How to scale attributes with normalization and standartization
Attributes in different scales are common in Machine Learning projects. For example, a medical record dataset can include in the columns weight, height, and blood pressure. These attributes have different units of measure and vary in different intervals, making their comparison difficult.
(more…) -
Big and Complex Projects Will Demotivate You, Build Simple and Small Projects
Many senior developers start in Machine Learning by building big and complex projects. An app powered by computer vision, sentiment analysis, or a recommendation system over a big database are examples of complex projects which involve Machine Learning.
It is perfectly all right to have big goals in Machine Learning. Indeed, we want to have these stunning projects in our portfolio. That’s why we practice and learn every day; because we want to be part of a great team creating incredible products.
But the problem is that big projects are time-consuming. They have a lot of details, and they require a lot of studies before you can make any progress. And because you stay a long time without any results, you will be demotivated and drop your project.
So if you want to keep your motivation and make real progress on your portfolio, you need to build simpler and smaller projects. These projects will be simple because you will need little theory to work on them. And these projects need to be small so that you complete them in a few hours or days. Yet, if you still have a big goal in mind, break it into smaller parts and make them little projects so that you can present your intermediary results.
How to make Machine Learning projects smaller
In this section, we present some ideas to simplify your projects so that you can finish your projects more quickly.
- Use a smaller dataset: the dataset you are using is too big, and you need special treatment for them. Choose a dataset that fits entirely in memory or select only some lines of the original dataset.
- Select a subset of attributes: select only a subset of attributes. Add more attributes to your project incrementally.
- Select a clean dataset: select a clean dataset so you can focus on modeling.
- Limit data preprocessing: you can spend life in preprocessing and feature engineering your dataset. Limit the techniques you will use so you can move on with the project.
- Test a subset of algorithms: you don’t need to apply all the algorithms you know in a single project. You can even dedicate a project to study one algorithm.
- Limit hyperparameter tuning: hyperparameter tuning is also a process that can take forever. Set a goal of how much you want to improve your model.
- Use simple tools: use the tools you already know.
- Targeted practice: focus one skill at a time. Practice loading and cleaning a dataset, calculating statistics, a single algorithm, and so on. Practice your skills separately and combine them in later projects
Conclusion
Building skills is an iterative process. After a cycle of practice, we need a reward so we can assess our progress. In Machine Learning, this is no different. Published projects are rewards for our hard work. Also, by completing projects, we can determine how much we learned and which are our knowledge gaps, so that we can fill them during the next cycle of practice.
This mechanism works better if our projects are small so we can complete them quickly (2 weeks at most). Bigger projects can take too much time to complete, and they can reveal too many gaps, which can demotivate us.
Therefore, we need to practice with small projects so we can keep a constant pace in building our skills and our motivation. As we gain practice, we can incrementally create more complex projects.
If you are not sure in which projects to work on, check some examples in the link below. There you can find a list of small projects you can complete in a few days or even minutes:
Small Machine Learning Projects
-
Small Machine Learning Projects
This page contains a list of links to small machine learning projects, which you can use as examples or to bootstrap a more significant projects.
- Create your first machine learning model in 5 minutes with Google Colab
- Introduction to Linear Regression With One Variable
- How to scale attributes with normalization and standartization
We will update this page as we publish new projects. Each blog post describes the project and contain links to Github repositories or Kaggle kernels.
Updated in 2020-03-19.
-
Introduction to Linear Regression With One Variable
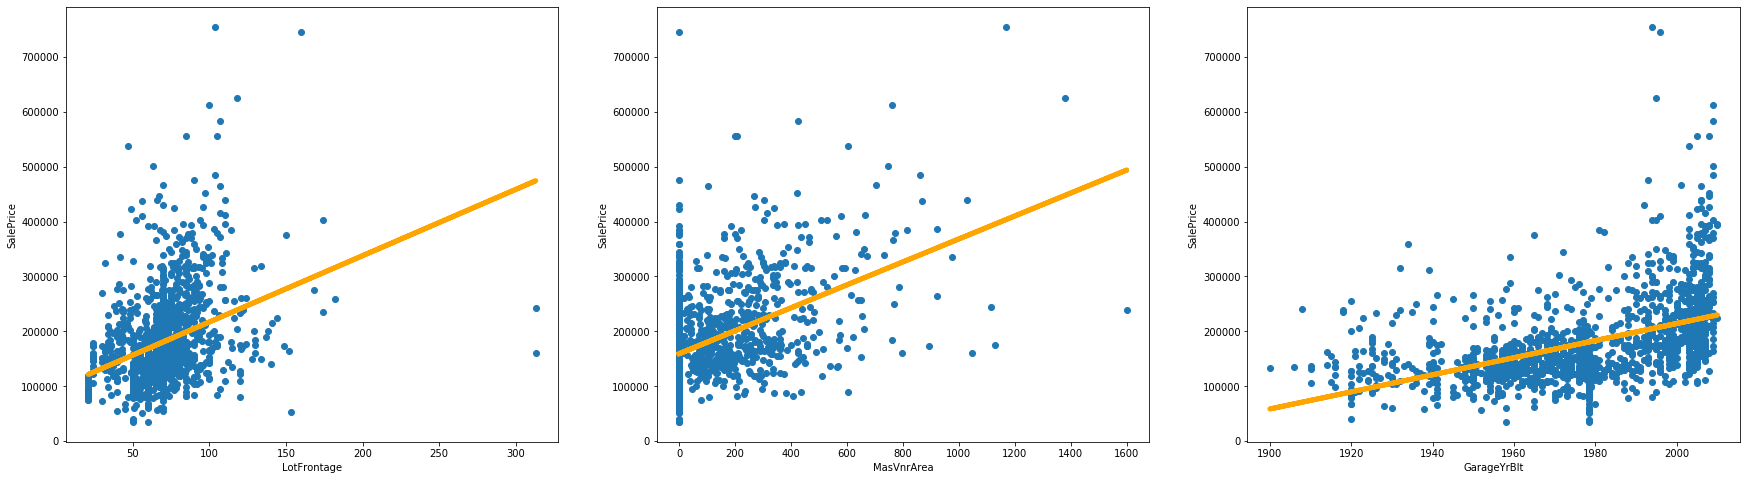
In this post, we present Linear Regression analysis using one variable example. The idea is to keep the examples as simple and straightforward as possible, so you can focus on the intuition behind Linear Regression and don’t get confused with too much data preparation or other details about tools and data manipulation. There are many algorithms to perform regression analysis, but Linear Regression is the simplest of them and the recommended algorithm to start with.
(more…) -
5 Reasons Why Google Colaboratory is the Right Tool for Beginner Data Scientists
With the growing value of big data and machine learning, Data Science attracted interest from professionals of various areas of expertise. You are one of these professionals, and then you studied linear algebra, calculus, probabilities, machine learning, and now you want to put this knowledge in practice.
All you want to do is to load some small data, perform some exploration, create some visualization, and train a simple model. Then you go to the Internet searching for the right tool to start your brand new data science project, and you find a lot of options. You install new software, libraries, and spend some time reading tutorials. But you still can’t decide which tool to use.
In the next sessions, we help you with this decision by listing five reasons that make Google Colab the right tool for beginner data scientists.
(more…) -
Create your first machine learning model in 5 minutes with Google Colab
Machine Learning is a very hot topic these days. Companies from different sectors and sizes, from startups to enterprises, are boosting their products and services with the help of machine learning.
As the demand for machine learning engineers grows, many experienced developers want to get to the field as fast as they can.
But as soon as they buy their first courses and books, they got frustrated. Instead of code and working examples, they face a bunch of math and statistics, topics that they haven’t applied since graduation.
Besides math, another source of frustration is the necessary software to build machine learning models. A few years ago, you had to install specialized software, buy powerful hardware and sometimes implement your algorithms from scratch.
The good news is that none of these is necessary to get started in machine learning. Current machine learning libraries abstract most of the math and algorithms you need so you can concentrate on the data flow instead of implementation details. Also, a web browser is everything you need to start creating your first machine learning models.
In this tutorial, we are going to create our first machine learning model using the most famous Python libraries and the Google Colab environment, so we don’t have to waste any time installing and configuring new software.
Google Colab
In this tutorial, we use the Google Colab tool to create Python notebooks. A notebook is a special file in which we can mix formatted text and Python code so we can create a rich documentation for our machine learning experiments. Also, we can plot charts directly to the notebook.
In order to create Python notebooks with Google Colab, all you need is a Google account and to click the link https://colab.research.google.com.
For a quick introduction to the Google Colab environment, watch the video Get started with Google Colaboratory:
Get started with Google Colaboratory Classifying Iris exemplars
In this tutorial we are going to build a machine learning model to determine to which species an Iris flower belongs to. The Iris dataset contains tabular data about characteristics of the flower exemplars like petal width and length, which are used as input to the model. The output will be an integer indicating representing one of the 3 possibilities of species: Iris Setosa, Iris Versicolour or Iris Virginica. The next sections will describe the construction of the model, step by step.
0. Setup
In this section we import the necessary libraries so you can build your model.
import numpy as np
import pandas as pd

from matplotlib import pyplot as plt

import seaborn as sns

from sklearn.model_selection import train_test_split
from sklearn.neighbors import KNeighborsClassifier
from sklearn.metrics import confusion_matrix

from joblib import dump, load
1. Load the data
The first step is to load the necessary data. Use the command read_csv() from pandas library to load the Iris dataset. After loading the data into a dataframe, show the top of the dataset. The dataset file URL is https://archive.ics.uci.edu/ml/machine-learning-databases/iris/iris.data.
cols = ['sepal_length', ' sepal_width', 'petal_length', 'petal_width', 'class']
df = pd.read_csv('https://archive.ics.uci.edu/ml/machine-learning-databases/iris/iris.data', names=cols)
df.head()
2. Explore and visualize the data
After loading the dataset into a dataframe in memory, the next step is to perform an exploratory data analysis. The objective of the EDA is to discover as much information as possible about the dataset. The describe() method is a good starting point. The describe() method prints statistics of the dataset, like mean, standard deviation, etc.
df.describe()
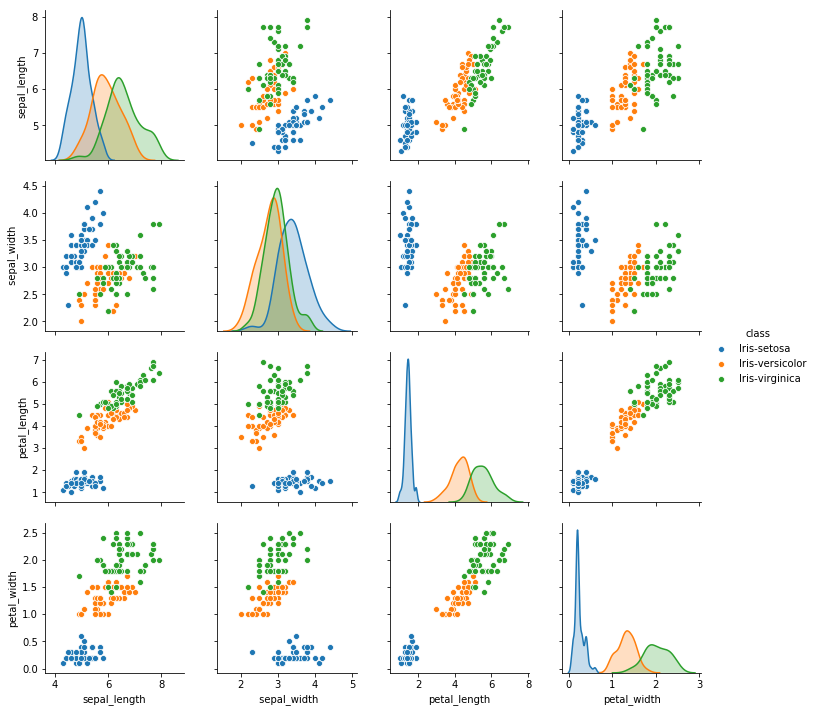
A very important tool in exploratory data analysis is data visualization, which helps us to gain insights about the dataset. The plot below shows the relationship between the attributes of the dataset.
sns.pairplot(df, hue='class');

Joint distributions of Iris dataset attributes Another interesting case of data visualization is use a heatmap to visualize the correlation matrix of the dataset.
sns.heatmap(df.corr(), annot=True)

Correlation matrix represented as an heatmap 3. Preprocess the data
Frequently, the dataset collected from databases, files or scraping the internet is not ready to be consumed by a machine learning algorithm. In most cases, the dataset needs some kind of preparation or preprocessing before being used as input to a machine learning algorithm. In this case, we convert the string values of the class column to integer numbers because the algorithm we are going to use does not process string values.
df['class_encod'] = df['class'].apply(lambda x: 0 if x == 'Iris-setosa' else 1 if x == 'Iris-versicolor' else 2)
df['class_encod'].unique()
4. Select an algorithm and train the model
After exploring and preprocessing our data we can build our machine learning model to classify Iris specimens. So, the first step is to split our dataframe in input attributes and target attributes.
y = df[['class_encod']] # target attributes
X = df.iloc[:, 0:4] # input attributes
X.head()
If in the previous step we splitted the dataframe by separating columns, in this step we split the data by rows. The method train_test_split() will split the X and y dataframes in training data and test data.
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.3,
                                                    random_state=0, stratify=y)

np.shape(y_train)
Then we use the datasets X_train and y_train to build a KNN classifier, using the KNeighborsClassifier class provided by scikit-learn. Because the machine learning algorithm is already implemented by the library, all we have to do is call the method fit() passing the X_train and y_train datasets as arguments.
m = KNeighborsClassifier()
m.fit(X_train, np.ravel(y_train))
Once the model is built, we can use the predict() method to calculate the predicted category of an instance. In this case, we want to predict the class of the first 10 lines of the X_test dataset. The return is an array containing the estimated categories.
m.predict(X_test.iloc[0:10])
We can use methods like score() and confusion_matrix() to measure the performance of our model. We see that the accuracy of our model is 1.0 (100%), which means that the model predicted correctly all cases of the test dataset.
m.score(X_test, y_test)
confusion_matrix(y_test, m.predict(X_test))
5. Save the model for later use
Finally, we want to save our model for later use. For example, we could embed our model into a webservice or mobile application. So we use the method dump() from the joblib package to save the model to a file.
dump(m, 'iris-classifier.dmp')

ic = load('iris-classifier.dmp')
confusion_matrix(y_test, ic.predict(X_test))
Conclusion
Although the simplicity of the Iris dataset, the steps demonstrated in this tutorial can be reproduced for practically any other dataset. The effort required on each step may vary, but the process is basically the same, so you can start practicing with simpler datasets and increase the complexity of your projects incrementally.
So, click the link below to open a ready to use template in Google Colab and create your first machine learning model right now:
First Machine Learning Model Template
Also, you can find a notebook version of this tutorial in the following link:
-
40 Resources to Completely Master Markov Decision Processes
The Markov Decision Process is the formal description of the Reinforcement Learning problem. It includes concepts like states, actions, rewards, and how an agent makes decisions based on a given policy. So, what Reinforcement Learning algorithms do is to find optimal solutions to Markov Decision Processes.
(more…) -
How to create FrozenLake random maps
Besides providing our custom map using the desc parameter, it’s also possible to create random maps for the Frozen Lake environment, as shown in the code below:
(more…) -
Gym Tutorial: The Frozen Lake
In this article, we are going to learn how to create and explore the Frozen Lake environment using the Gym library, an open source project created by OpenAI used for reinforcement learning experiments. The Gym library defines a uniform interface for environments what makes the integration between algorithms and environment easier for developers. Among many ready-to-use environments, the default installation includes a text-mode version of the Frozen Lake game, used as example in our last post.
(more…)